|
Mukilan Karuppasamy
I'm a Research Scientist at FastcodeAI, where I built Hydra, a speech-to-speech model for SmallestAI. My research spans multimodal LLMs, interpretability, and robustness. Previously, I was a predoctoral researcher at IISc Bangalore with Prof. Anirban Chakraborty, working on visual instruction tuning for MLLMs. Before that, I built the first interpretable video action classifier with Prof. C.V. Jawahar (IIIT Hyderabad), large-scale noise robustness analysis on vision-language models with Prof. Yogesh Rawat (CRCV, UCF), and explored distributed message passing as a MITACS Globalink Fellow with Prof. Amine Mezghani and Prof. Faouzi Bellili (University of Manitoba, 2023). |
|
ResearchI'm interested in mechanistic interpretability, representation learning, and robustness analysis. My current interest lies in understanding the theoretical basis of interpretability in overparameterized deep neural networks. Some papers are highlighted. |
|
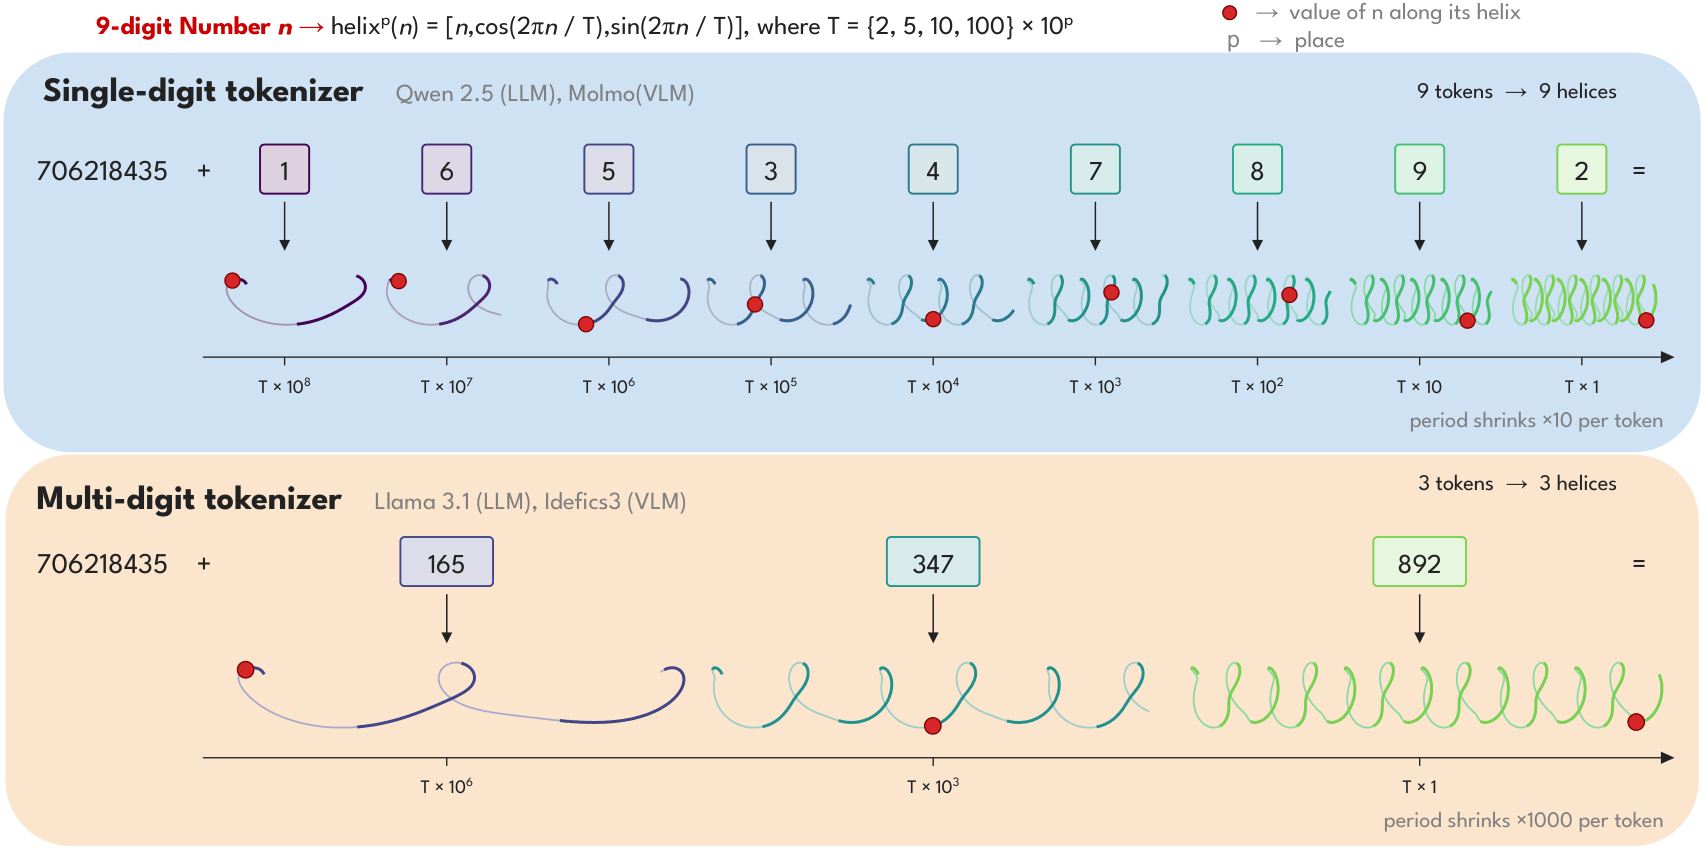
Understanding multi-token number representations in autoregressive model
Mukilan Karuppasamy, Siddhesh Choudhary, Adithyan CG, Anirban Chakraborty, Arjun Jain. Under Review (A* Conference) Comprehensive analysis of VLM/LLM across tasks on number representations when numbers are split across tokens. |
|
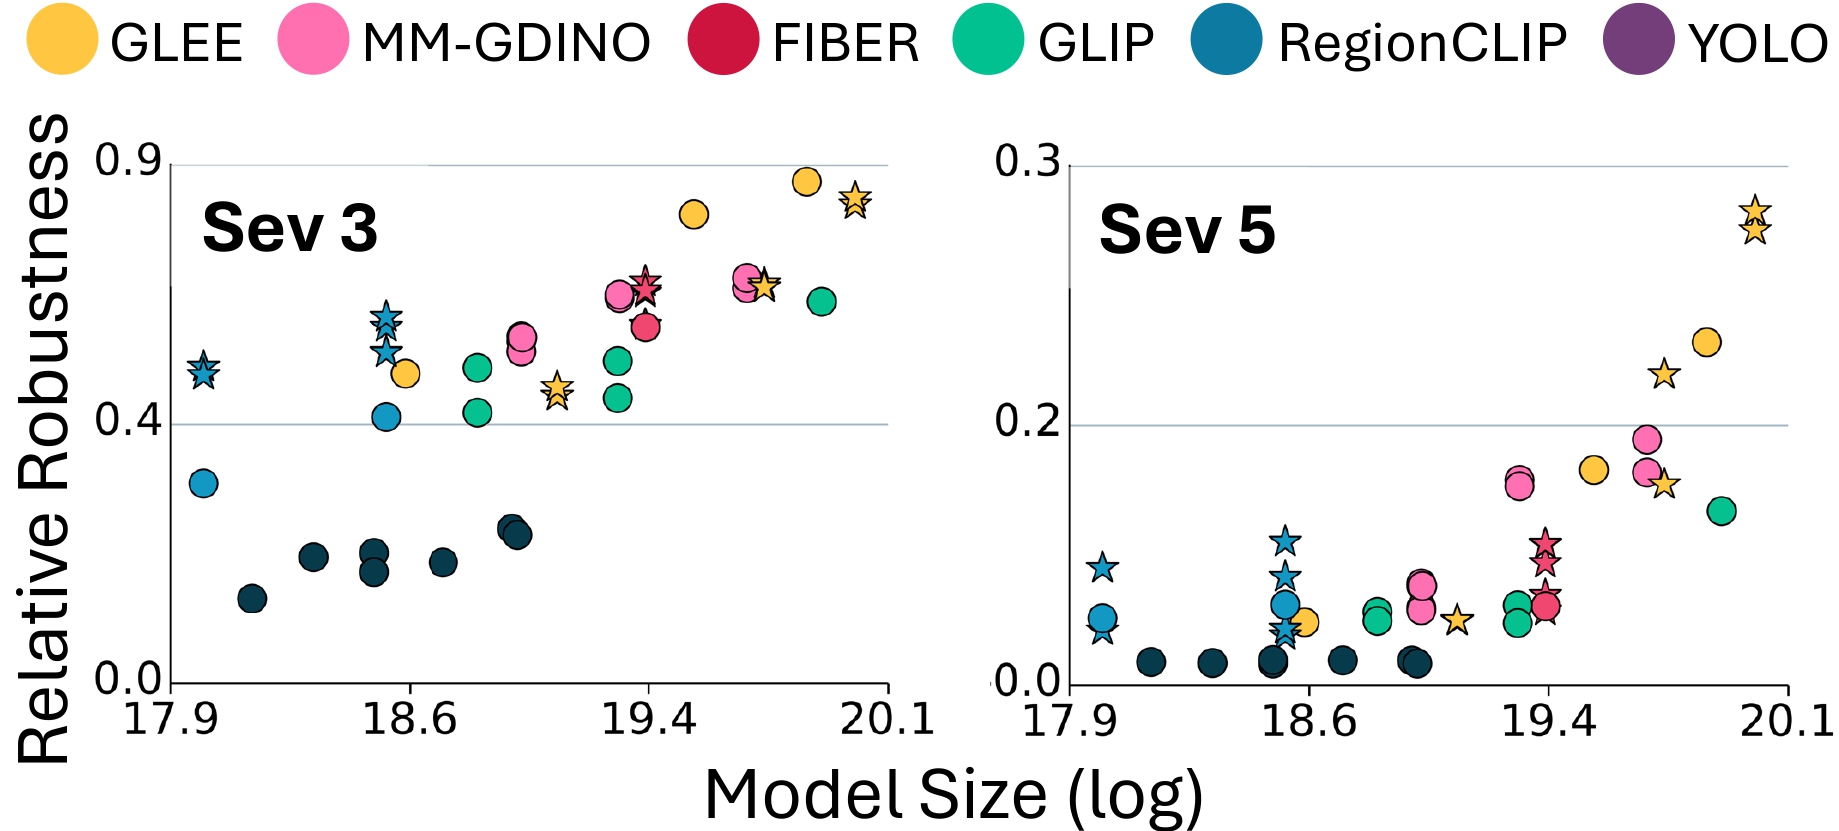
Robust onion: Peeling Open Vocab Object Detectors Under Noise
Priyank Pathak*, Mukilan Karuppasamy*, Aaditya Baranwal, Shruti Vyas, Yogesh S. Rawat, * equal contribution, ECCV 2026 project page / arXiv / code We critically examine the vulnerability of SOTA Zero-Shot Object Detectors with 50 different backbones to resolution degradation (`pixelation'). Three key takeaways are 1) The choice of backbone alone can substantially enhance robustness, while prompting (language) plays a minimal role. 2) Robustness is also a function of the dataset/domain of images at inference. 3) Cross-exchange of vision features within backbone helps in improving robustness. |
|
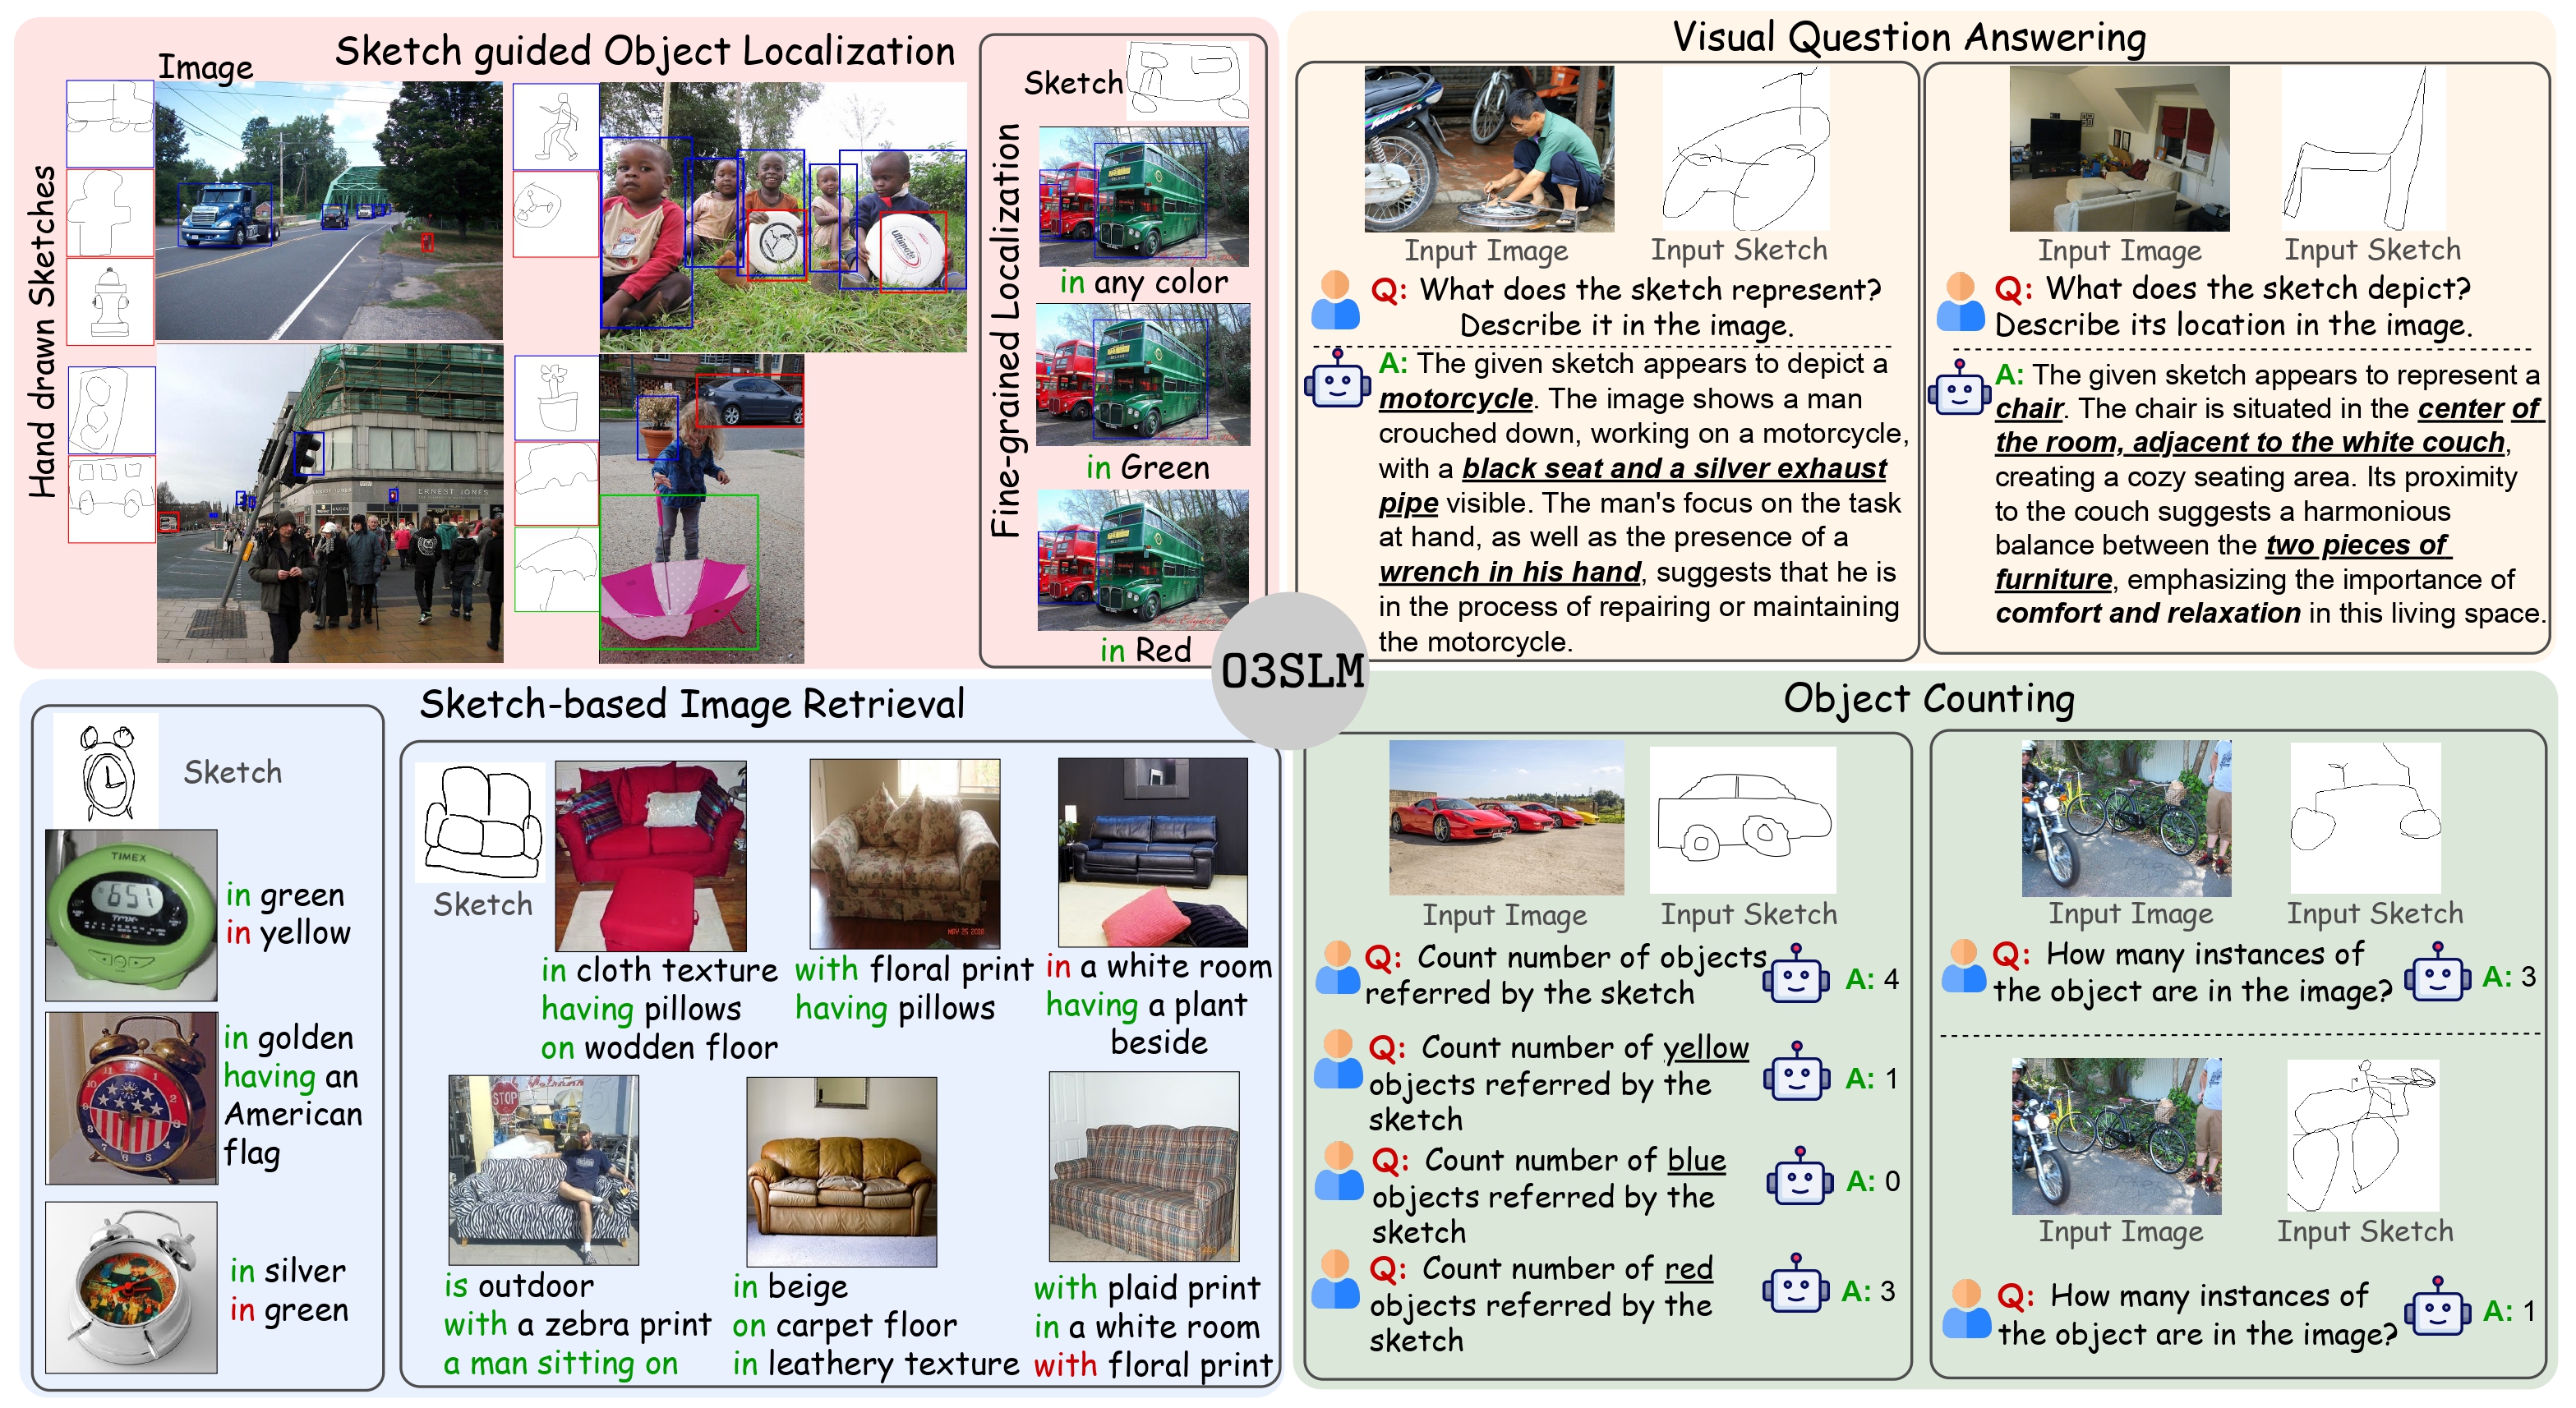
O3SLM: Open Weight, Open Data, and Open Vocabulary Sketch-Language Model
Rishi Gupta, Mukilan Karuppasamy*, Shyam Marjit*, Aditay Tripathi, Anirban Chakraborty, * equal contribution AAAI 2026 project page / arXiv / code Proposed a large scale sketch based pretraining and visual instruction tuning dataset with 30M instances. Developed a state-of-the-art sketch-based multimodal model that can perform detection, Counting, VQA, and SBIR with any crude, hand-drawn sketches as the query instead of natural language. |
|
Towards Safer and Understandable Driver Intention Prediction
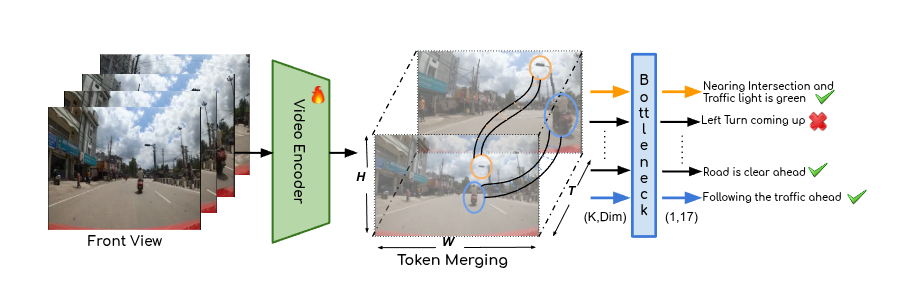
Mukilan Karuppasamy, Shankar Gangisetty, Shyam Nandan Rai, Carlo Masone, CV Jawahar, ICCV, 2025 project page / arXiv / code Proposed a concept based inherently intrepretable model for Video models using concept bottleneck model and token merging. This was applied in Driver Intention Prediction task. |
|
Distributed Vector Approximate Message Passing
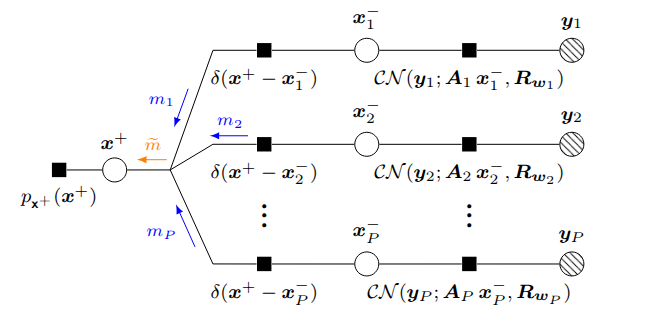
Mukilan Karuppasamy, Mohamed Akrout, Amine Mezghani, Faouzi Bellili, ICASSP, 2024 code / paper Derived a collaborative signal estimation from multiple agents with different measurement channels through distributed message passing algorithm. |
ServicesReviewer - AAAI 2026, AAAI 2027, ICLR 2027 |